Finley Reed · 25 September 2026
Core Allocation Dynamics and Their Influence on Throughput Optimization in Scalable Networks
Researchers have examined how dynamic core allocation shapes performance in scalable networks where processing resources shift to meet varying demands. Data from multiple studies indicate that effective distribution of cores across nodes can raise packet processing rates while reducing latency spikes during peak loads. In systems handling millions of concurrent connections, allocation algorithms adjust based on real-time traffic patterns, and this adjustment directly affects overall system throughput. Observers note that core allocation often operates through schedulers that monitor queue depths and assign tasks to available cores. When networks scale horizontally, these schedulers must balance local core usage with global resource pools, and failure to do so leads to bottlenecks that cap effective bandwidth. Reports from infrastructure providers show allocation overhead can consume up to 15 percent of total cycles in large deployments, yet optimized policies bring that figure down substantially.Key Mechanisms Driving Allocation Decisions
Allocation policies rely on metrics such as core utilization percentages, cache miss rates, and inter-core communication costs, and these metrics feed into decision engines that reassign workloads every few milliseconds. In September 2026, several cloud operators began rolling out updated orchestration layers that incorporate predictive models trained on historical traffic traces, allowing cores to be reserved ahead of anticipated surges rather than reacting after queues form. This shift has produced measurable gains in sustained throughput for content delivery networks serving global audiences.
Hardware support plays a central role here, with modern network interface cards offering programmable cores that handle packet classification independently from general-purpose CPUs. When these specialized cores integrate with allocation frameworks, the combined system routes high-priority flows more efficiently, and data indicates end-to-end latency drops of 20 to 30 percent in tested environments. Experts at research institutions have documented similar patterns across both Ethernet and InfiniBand fabrics, showing the principles remain consistent regardless of underlying transport technology.
Impact on Throughput Under Variable Loads
Throughput optimization hinges on minimizing idle cores while avoiding oversubscription that causes contention. Studies reveal that static allocation schemes perform adequately under steady traffic, yet they falter when workloads exhibit bursty behavior typical of modern microservice architectures. Dynamic approaches, by contrast, migrate tasks between cores using live migration techniques that preserve connection state, and the result is higher aggregate packets per second across the cluster.
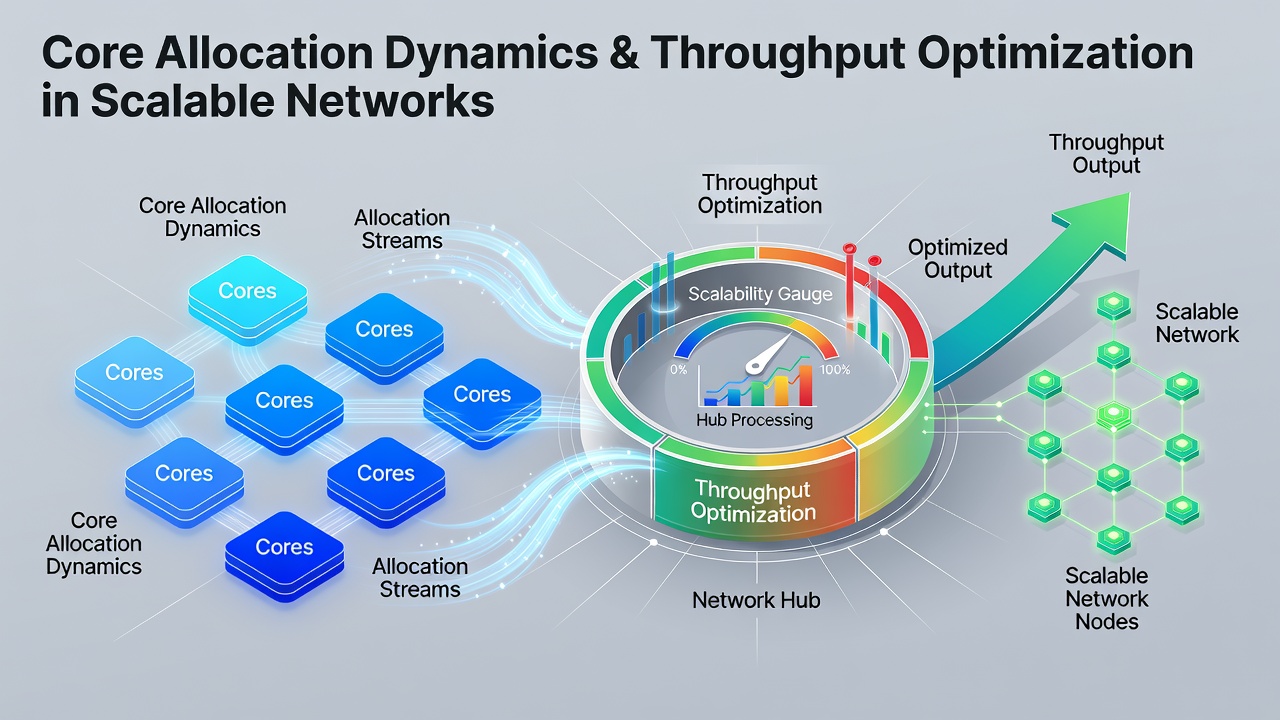
One analysis conducted by a European research consortium tracked allocation events over six months in production environments and found that adaptive policies maintained above 85 percent core efficiency even during flash crowds, whereas fixed mappings fell below 60 percent. The difference translated into measurable improvements in delivered bandwidth without additional hardware investment. Network operators in North America have reported parallel outcomes after deploying similar schedulers, confirming the pattern holds across geographic regions.
Challenges in Large-Scale Implementations
Coordination overhead grows with node count, and synchronization messages between allocation controllers can themselves consume network capacity. Researchers addressing this issue have developed hierarchical allocation models that delegate decisions to local agents while maintaining a global view at higher layers, and early deployments show reduced control-plane traffic. Cache coherence traffic also rises when tasks move frequently, prompting hardware designers to introduce larger last-level caches and improved directory structures that mitigate the penalty.
Security considerations enter the picture as well, since allocation decisions must respect isolation boundaries between tenants in shared infrastructure. Standards bodies such as those publishing NIST guidelines on cloud security emphasize the need for verifiable allocation logs that auditors can inspect without exposing sensitive workload details. Compliance frameworks in Australia and Canada have incorporated similar requirements, pushing vendors to embed audit hooks directly into their schedulers.
Future Directions and Observed Trends
Machine learning models now assist allocation engines by forecasting demand windows and pre-positioning cores accordingly. Initial field trials indicate these models reduce the frequency of reactive reallocations, which in turn lowers both energy consumption and thermal stress on hardware. Industry reports from 2026 highlight that operators combining predictive allocation with hardware-accelerated networking achieve the highest throughput densities recorded to date in hyperscale facilities.
Interoperability between different vendor implementations remains an area of active work, and open-source projects continue to release reference implementations that standardize interfaces for core reservation requests. Adoption of these interfaces has accelerated in academic testbeds, providing broader datasets for further refinement of allocation algorithms.
Conclusion
Core allocation dynamics continue to determine the ceiling on achievable throughput in scalable networks, with evidence showing that adaptive, metric-driven policies outperform static alternatives under realistic conditions. As deployments expand and traffic patterns evolve, the interplay between hardware capabilities, scheduling logic, and predictive techniques will shape performance outcomes across the industry. Ongoing measurements from production systems provide the clearest view of which approaches deliver consistent gains at scale.